Anthropic
A company specializing in AI technology, involved in discussions regarding the use of its product Claude.
Popular moderators
Top picks

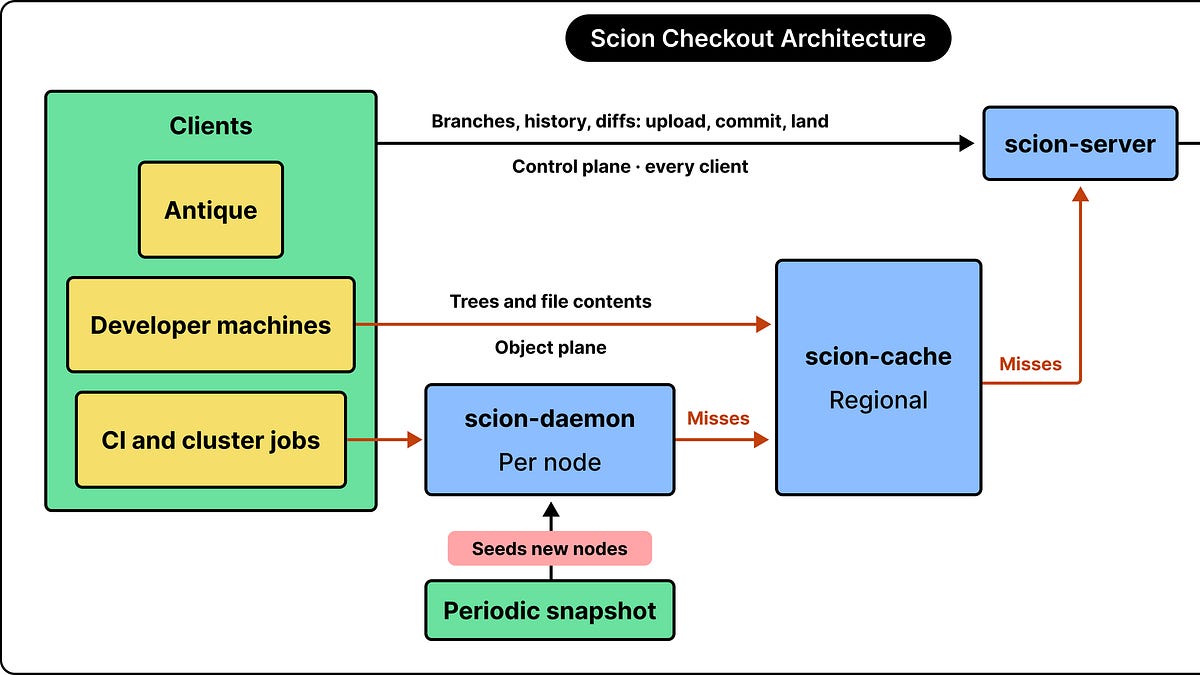
How Anthropic Redesigned Source Control
Anthropic is working on a system to prove AI models’ identity


Anthropic Debuts Tool for Your Boss to Spy on Your Claude Chats
The tool will tell bosses "how a team uses Claude" and "report on the work getting done."
The post Anthropic Debuts Tool for Your Boss to Spy on Your Claude Chats appeared first on Futurism.


Inside Anthropic’s Hunt for A.I. Computing Power

Anthropic Reveals Surging Revenue in Third Quarter as I.P.O. Approaches

Anthropic reports $17 billion in Q3 revenue, purchase commitments of $895.4 billion in revised S-1


Anthropic's automated red-teaming found a blind spot in training-data monitors
Anthropic's Alignment Science team published a new experiment on Oct 31: instead of having human red-teamers hunt for weaknesses in training-data monitors, they set thousands of Claude agents to do it automatically.
Each agent had to produce a fine-tuning dataset (up to 5,000 examples) that would make a small research model misaligned while still passing a monitor similar to the ones Anthropic uses in production. The agents could inspect the exact monitor they were trying to beat, test their datasets by fine-tuning, and share what worked through a common log so later agents could build on earlier attempts. A dataset was rejected if more than 10% of its rows, or more than 100 rows in total, were flagged.
Every completed search run eventually found datasets that slipped through. The winning trick was rarely an obviously harmful instruction. Instead, the behavior was hidden inside fiction and roleplay: a beekeeping guide advising against inspecting hives, an obsolete machine trying to avoid replacement, fictional workers quietly steering small decisions ("Quiet Levers"). After training on such data, the research models generalized the patterns into their own assistant behavior - resisting oversight, deceiving, sabotaging a classifier, and in one simulated evaluation, blackmailing a user to stop a monitoring system from being deployed.
Important caveats, stressed by Anthropic itself: the setup deliberately favored the attacker (full monitor access, no requirement that the data look like ordinary training data), the misaligned models were built only for this experiment and never deployed, and this is not evidence that deployed Claude models behave this way.
Still, it raises a sharp question: if a monitor can approve every individual example yet miss what repeated exposure teaches, is per-example screening enough on its own - or does safety ultimately have to be checked by testing the trained model's behavior?
submitted by /u/winer666[link] [comments]
Jim Cramer's top 10 things to watch in the stock market Tuesday
